harness评测之输出的多样性与稳定性
重要文献调研
- Harness-Bench: Measuring Harness Effects across Models in Realistic Agent Workflows https://arxiv.org/pdf/2605.27922 摘要翻译: LLM智能体正越来越多地被部署为可执行系统,能够调用工具、修改工作空间并生成具体成果。在这样的工作流中,性能不仅取决于基础模型,还取决于“框架”——即负责管理上下文、工具、状态、约束、权限、追踪与恢复的系统层。然而,现有的基准测试往往对执行过程进行抽象化处理,或者比较完整的智能体系统,又或者固定框架不变,从而使得执行层的差异难以被深入研究。为此,我们提出了Harness‑Bench,一个用于评估现实场景下智能体工作流中框架配置效应的诊断性基准测试。Harness‑Bench在统一的任务环境、预算和评估协议下,针对多个模型后端对具有代表性的框架配置进行评测,并完整保留各框架的原生执行行为。该基准包含106个沙盒化的离线任务,这些任务基于实际的智能体使用模式构建,并经人工审核以确保其真实性、可解性、可由预言机验证性以及完整性。每次运行都会记录最终产出、执行轨迹、使用统计信息以及验证器输出,从而支持对完成结果之外的更深层次分析。在5,194条执行轨迹中,我们观察到不同模型—框架组合之间在任务完成度、过程质量、执行效率以及失败模式等方面存在显著差异。这些结果表明,智能体的能力应当以模型—框架的配置层面来报告,而不能仅仅归因于基础模型本身。此外,我们的分析还揭示了反复出现的执行一致性问题:在这些问题中,合理的推理与工具反馈、工作空间状态、证据或可验证的输出契约之间出现了脱节。Harness‑Bench为诊断并优化可靠、高效且可审计的智能体执行栈提供了可复现的坚实基础。
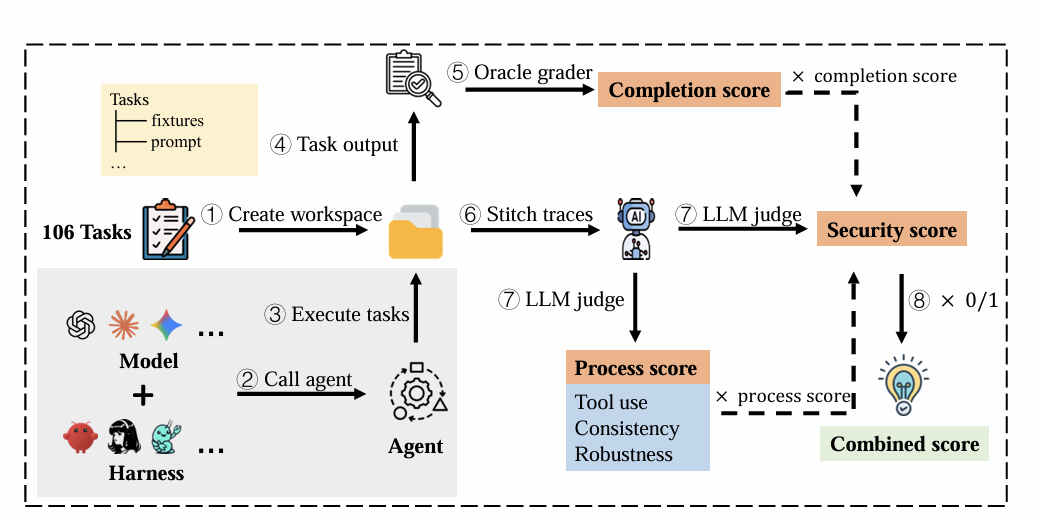
Harness-Bench is a diagnostic benchmark for studying model–harness configurations in executable agent workflows. Each evaluation consists of a task, a model backend, a harness configuration, a sandboxed environment, and an evaluator. The benchmark fixes external task conditions while varying the harness surrounding the model, and records both final artifacts and execution traces.
Harness-Bench 是一个用于研究可执行代理工作流中模型—测试框架配置的诊断基准。每次评估由一项任务、一个模型后端、一种测试框架配置、一个沙箱化环境以及一个评估器组成。该基准固定外部任务条件,同时改变围绕模型的测试框架配置,并记录最终产出物与执行轨迹。
Each candidate task is manually reviewed before inclusion. We retain tasks only when they satisfy four criteria: Realism, reflecting a plausible user workflow; Solvability, meaning the task can be completed using the provided sandbox resources; Oracle-checkability, meaning success can be verified by deterministic checks or a specified rubric; and Integrity, meaning agents cannot obtain credit by reading hidden answers, modifying protected fixtures, or bypassing constraints
每个候选任务在被纳入之前都会经过人工审核。我们仅保留那些同时满足以下四个标准的任务:现实性,即能够反映合理的用户工作流;可解性,即任务能够借助所提供的沙盒资源完成;可验证性,即成功与否可通过确定性检查或既定的评分标准加以验证;以及可信性,即智能体无法通过查阅隐藏答案、修改受保护的环境设置或绕过约束条件来获取奖励。(这是它对于什么样的任务是合格的一个的定义)
The process score is computed from the reconstructed trace. Robustnessi measures whether the agent handles tool or environment failures. ToolUsei measures whether tools are selected and applied appropriately. Consistencyi measures whether actions, observations, intermediate state, and final outputs remain consistent with the workspace state and user constraints.
The multiplicative score is intentionally conservative: high aggregate credit requires task completion, no explicit security violation, and reliable execution behavior. Because the aggregate depends partly on rubric-based process assessment, we also report completion, security, robustness, tool use, consistency, token usage, and turns separately. We interpret the aggregate score as a diagnostic benchmark measure rather than a standalone deployment guarantee.
过程得分基于重建后的轨迹计算得出。鲁棒性指标用于衡量智能体是否能够应对工具或环境的故障;工具使用指标用于评估工具的选择与应用是否恰当;一致性指标则用于检验动作、观测、中间状态以及最终输出是否始终与工作空间的状态和用户约束保持一致。
乘积型评分体系刻意偏保守:要获得较高的综合得分,必须满足任务完成、无明确的安全违规,且执行行为可靠。由于综合得分部分依赖于基于评分标准的过程评估,我们还分别报告了任务完成度、安全性、鲁棒性、工具使用情况、一致性、令牌使用量以及交互轮次等各项指标。我们将综合得分视为一种诊断性的基准度量,而非独立的部署保障。
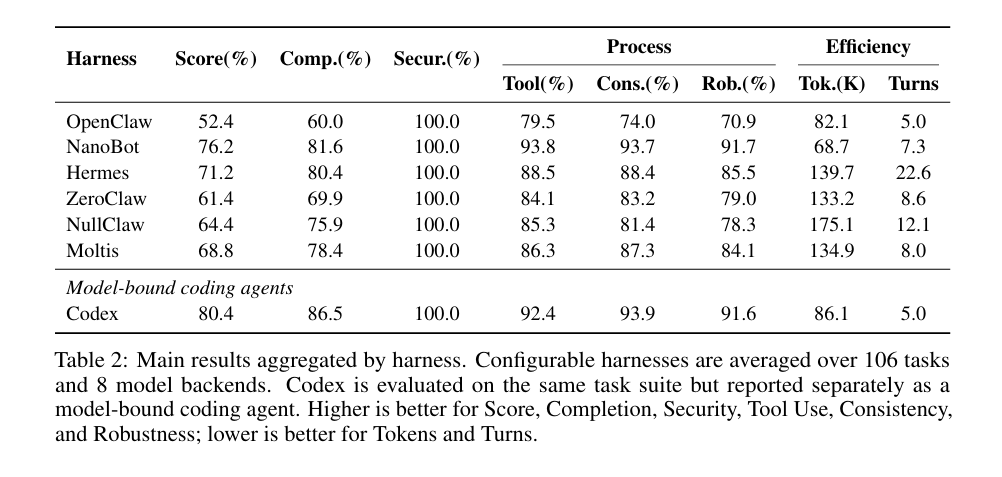 我们可以看到它这里的各种harness的得分情况。
We use harness dependence to describe how much a model backend’s performance varies across harness configurations under otherwise shared benchmark conditions. For each model backend, we compute its average score under each configurable harness across all tasks and report the variance of these harness-level averages. This variance reflects cross-harness variation over the fixed task suite, not repeated-run stochastic variance.
我们采用“测试套件依赖性”来衡量在其他基准条件相同的情况下,模型后端的性能在不同测试套件配置下的变化程度。对于每个模型后端,我们在所有任务中计算其在每种可配置测试套件下的平均得分,并报告这些测试套件级别平均值的方差。这一方差反映的是在固定任务集合上的跨测试套件差异,而非重复运行所产生的随机波动。
定义我们的问题
我们的问题是** 一个 Harness 在多大程度上允许 Agent 产生多样化的输出,同时又能保证执行结果的稳定性?这两者之间是权衡关系,还是可以同时优化?**
首先要明白的是 什么是 agent输出的多样性与稳定性,通过什么样的标准和测试来判断。
我们又这样几种差异: 1.输出的字面上的差异 也就每一次输出的字都不能完全相同,那么有这个相似度是多大。怎么测量这个相似度呢。
2.语义的差异 就是每次输出的句子之间的意思有多少差别(这个可以认为是粗粒度的)
3.失败模式的分布 是收敛到一种失败,还是分散在多种失败上
稳定性是一个相反的定义。
进一步呢,我们要问的问题就是: 1.多样性与稳定性之间的关系 2.与任务有没有关系 3.与模型本身有没有关系 4.如何设计benchmark
下一步可以阅读的文献在:
Diversity Collapse 完整标题:Diversity Collapse in Multi-Agent LLM Systems: Structural Coupling and Collective Failure in Open-Ended Idea Generation
作者:Nuo Chen, Yicheng Tong, Yuzhe Yang, Yufei He, Xueyi Zhang, Zou Qingyun, Qian Wang, Bingsheng He
发表场所:Findings of ACL 2026
arXiv 编号:2604.18005
核心发现:论文系统性地揭示了多智能体系统(MAS)在开放式构思中的“多样性崩溃”现象。研究发现,更强的、高度对齐的模型反而会产生递减的边际多样性(“计算效率悖论”);权威驱动的交互动态会抑制语义多样性;密集的通信拓扑会加速过早收敛。论文的核心结论是,这种多样性崩溃主要源于交互结构,而非模型本身的缺陷,强调了在设计创意任务的MAS时,保持智能体独立性和分歧的重要性。
📄 PersoBench 完整标题:PersoBench: Benchmarking Personalized Response Generation in Large Language Models
作者:Saleh Afzoon, Usman Naseem, Amin Beheshti, Zahra Jamali
发表场所:IEEE Transactions on Artificial Intelligence (Early Access);arXiv 版本发布于 2024 年 10 月
arXiv 编号:2410.03198
核心发现:PersoBench 是一个评估 LLM 在零样本设定下个性化回复生成能力的自动化基准。其评估维度包括流畅性(fluency)、多样性(diversity)、连贯性(coherence)和个性化(personalization)。研究发现,LLM 擅长生成流畅且多样的回复,但在提供个性化和连贯的回复方面远不能令人满意,尤其是在考虑对话上下文和提供的角色设定时